Training AI models with synthetic data: benefits, challenges and opportunities
The benefits, challenges and opportunities of training AI models with synthetic data, explained in an article from the Neurally blog.
Contents
When it comes to AI, the quality and quantity of data are fundamental: the more examples a model sees, the more accurate it becomes. But there is a problem: collecting real datasets is often expensive, slow and subject to privacy restrictions. This is where synthetic data comes in: artificially generated images or data used to boost training. This data is genuinely revolutionising the way we train artificial intelligence models. Let’s look at the benefits, challenges and opportunities of this approach.
What is synthetic data and why does it matter?
Synthetic data is data created artificially through algorithms, simulations or generative models, replicating as closely as possible the characteristics of the real data it refers to. It is particularly useful when:
-
real data is scarce, as in rare or hard-to-reproduce scenarios (for example road accidents or medical anomalies);
-
privacy is critical, to avoid exposing sensitive information such as faces or medical records;
-
collection and annotation costs are high.
Let’s take a concrete example. In facial recognition, creating synthetic images of faces with different angles, lighting or expressions makes it possible to train accurate models without violating users’ privacy.
Data augmentation: a complementary solution
A crucial point in training AI models is understanding how models perceive data. For a model, a small variation, such as rotating an image by one degree, is equivalent to a completely new example. This is where data augmentation, with tools such as Albumentations, becomes essential. This framework lets you create synthetic variations of existing images (rotations, zoom, lighting changes) and expand existing datasets by manipulating real images to create new ones, improving the model’s ability to generalise and handle real-world scenarios.
Tools such as Albumentations, TensorFlow, PyTorch Transforms, let you apply transformations such as:
-
Rotations and translations that change the orientation of images
-
Zooming in/out to simulate changes in distance
-
Distortions and noise, to imitate difficult capture conditions.
These techniques help models handle the variations they will encounter in the real world. For example, a pedestrian detection model trained only on images taken in ideal conditions will fail in rain or poor visibility. Data augmentation fills these gaps.
Practical applications: a focus on computer vision
Synthetic data is used in many sectors, but in computer vision it is essential. In particular in:
-
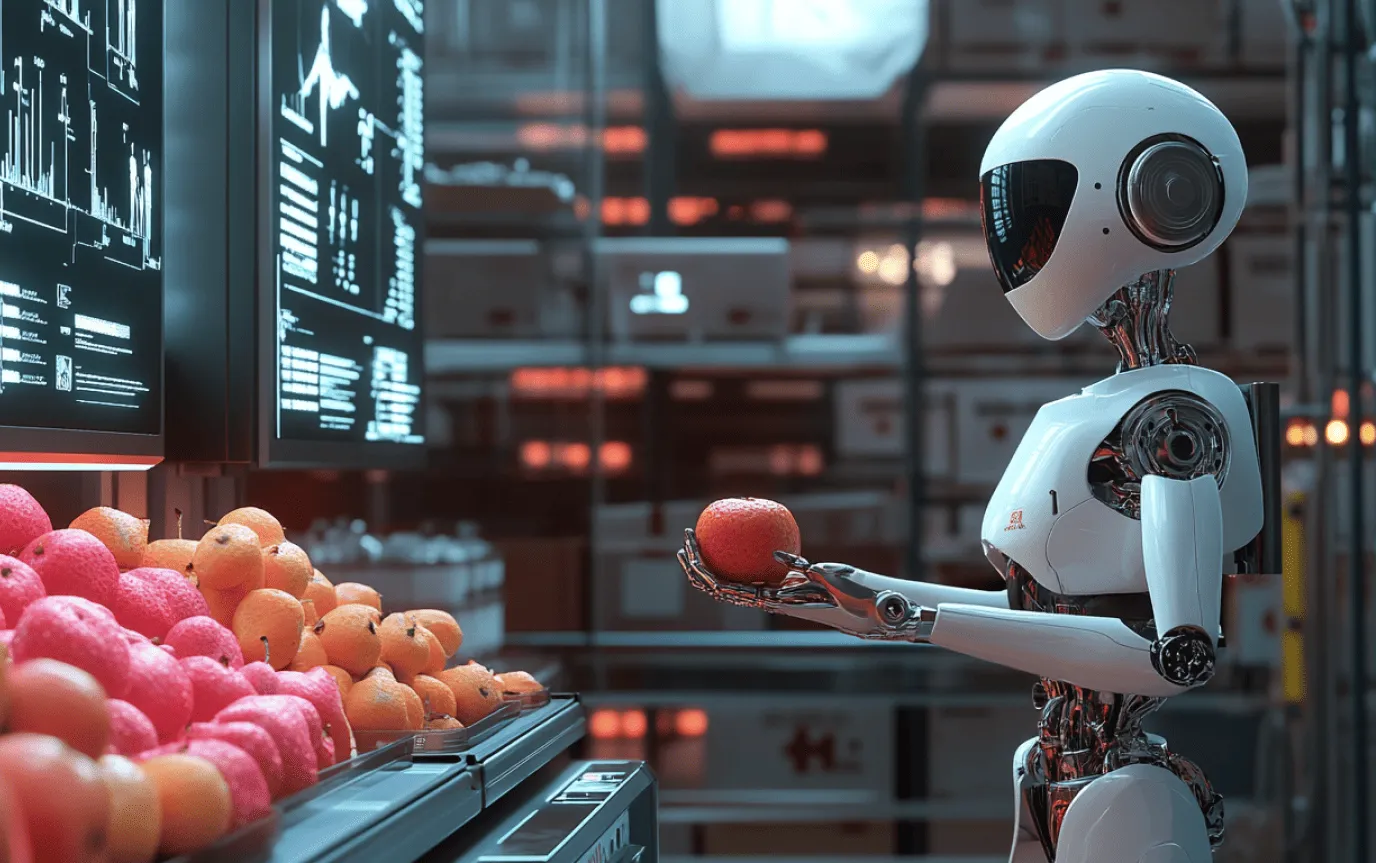
Robotics: virtual environments simulate warehouses or factories to train robots to handle objects or navigate complex spaces
-
Healthcare: generating synthetic medical scans, such as X-rays or CT scans, helps train diagnostic models without relying on real patients
-
Food: generating synthetic images of fruit increases the accuracy with which “defective” produce is handled.
Synthetic data and generative AI
Beyond computer vision, synthetic data is also crucial for generative models, such as GANs (Generative Adversarial Networks). One example is training models to create realistic images for fashion or architecture, or to generate audio or video content.
Another innovation is the use of multimodal models, where synthetic data such as generated images and descriptions improves the model’s visual understanding.
The benefits of using synthetic data
1. Data privacy and security
-
Protection of sensitive data: since synthetic data does not derive directly from real data, it contains no identifiable personal information, making it ideal for applications that must comply with privacy regulations
-
Lower risk of breaches, since it is not linked to real individuals.
2. Accessibility and availability
- Easy generation: synthetic data can be created quickly and at scale, solving problems of scarcity, unavailability or restrictions.
3. Better AI model performance
-
Larger datasets, improving the training of machine learning models
-
Data balancing: synthetic data can be generated for rare or under-represented classes, improving the quality and accuracy of predictions
-
Simulation of complex and hypothetical scenarios that may not exist in real data.
4. Lower costs and shorter timescales
-
Savings on data collection costs, since generating synthetic data is often cheaper
-
Speed: production is fast and scalable compared with traditional collection methods.
5. Flexibility and customisation
-
Control over the data, tailoring synthetic datasets to specific needs
-
Realistic test environments, with simulations in specific, controlled conditions to test software systems, applications or models.
Challenges and future prospects
Despite the benefits, synthetic data is not perfect. There is a risk of introducing poorly designed biases, which can create artefacts or distortions, or of failing to capture the complexity of the real world. Validating the reliability of synthetic data is complex and costly.
Finally, there is mistrust of synthetic data, especially in regulated sectors, because there are no formal standards for assessing its quality.
Today, the key to overcoming these challenges lies in combining synthetic and real data, to ensure balanced and reliable training.
The technological future promises major developments, with increasingly advanced and accessible tools for generating high-quality synthetic data, which will drive a new generation of AI models capable of tackling the most complex challenges in every sector.
Want to know how to build your own model using synthetic data?
 Martina Biscuola